Saturday, August 25, 2012

Gender in Advertising Images: The Devil is in the Detail

My Saturday was unbalanced already at breakfast, while reading the Economist and drinking my orange juice. On page 67 of the August 25-31, 2012 issue, I discovered that TU Delft is recruiting a Professor of Safety Science (good news!). Unfortunately, whoever designed this ad has made some unconventional decisions (not such good news).

The most obvious "bug" is the choice to include in the advertisement an image of a person. Since this misstep is a useful illustration of the limitations of visual depictions in multimedia, I decided to dedicate a blogpost to discussing it.

At first consideration, it seems obvious that our university should advertise using image of people. One of the reasons that I love working at TU Delft is the emphasis on solving societal problems. Using pictures containing people and not just technology wherever possible seems to be a good strategy for getting the importance of our work to address human and social challenges across.

However, a major limitation for visual depictions such as images and videos is "the curse of instance  depiction". Basically, it is impossible to create such visual imagery without committing yourself to depicting a full range of details. You can't get across and abstract concept, for example, "car" without actually committing yourself to an instance of a single car existing in the real world, which you take to stand for all cars. Instead, you are going to need to show in your image a specific type, make and model.

Here, the concept that the ad is trying to convey is "professor". The "type, make and model" chosen to convey this concept are an adult of a certain gender and a certain age group, wearing glasses. It seems plausible that the person designing the ad was aware of the problem of instance depiction. The decision to use a model with a shaved head makes it possible to avoid depicting the hair color, which could serve to further specify the ethnic background or the age.

However, it is extremely difficult, if not impossible, to "hedge" on the gender question in images of the real world. A person depicted in a daytime work setting will generally be identifiable as a male person or a female person.

If we assume that the process by which we choose and interpret images that are being used to represent categories follows prototype theory, then the choice of a male to represent a TU Delft professor is no just unbalancing for the reader of the advertisement, but is very serious indeed. Prototype theory tells us that in our cognitive representations, some members of conceptual categories are more salient than others. We think of them first when we think of a category and we react to them more quickly when confirming category membership.

The use of a male person in this advertisement sends the message that males are the canonical professors at the TU Delft. Although men are clearly in the majority in the faculty, there is not any sort of a conscious intention at the university to keep the situation that way. In fact, I have the impression that everyone is working to shift their idea of how can be a professor to encompass a diverse demographic more directly representative of the general population.

Visual depictions in multimedia, i.e., images depicting the real world, are limited in what they can express because they deprive us of the possibilities of leaving certain details unpecified. What we have is a reversal of the saying "A picture is worth a thousand words." Instead, the spoken or the written word is able to express more in this case because human language can directly convey concepts without having to make use of specific instances to do so. In effect, the possibility for ambiguity or underspecification is makes human language more expressive that multimedia.

And so, the saying "The devil is in the detail" takes on a new shade of meaning.

What to do about the advertisement? I advise having a closer look at some advertising guidelines. Advertising Standards Canada, a non-profit self-regulation body for advertising, has a helpful list of guidelines for balancing gender representations in advertising online and surely Europe has a similar set of guidelines.

An "quick and dirty" solution is to look to see how other universities advertise. In the Economist, a general tendency to avoid imagery is readily apparent. For example, next to the TU Delft advertisement is a classical advertisement for Harvard faculty positions, whose only graphic content in the Harvard Business School logo.

I was cheered up again when my Google Googles app confirmed for me that the logo used was from the business school (i.e., distinct from the main Harvard Logo). It is my first use of Google Goggles for something other than just playing around with while hanging out with my multimedia information retrieval colleagues.

For completeness, I note a less obvious bug. The advertisement contains the text "Maximum employment: 38 hours per week (1 FTE)" In order to interpret this text, you need to know that "FTE" stands for "full time equivalent". 1 FTE means this position is a full time job. Contrary to what the text implies, no one the Safety Science processor to working 38 hours a week.

Wednesday, August 8, 2012

Worry-Free Social Sharing for Social Networks

 Flickr: Phil Wiffen
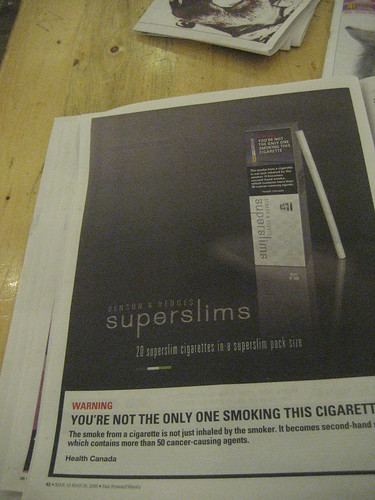
Quite a few people have heard me say that social networks should come with a warning: when you sign up, for example for Facebook, the company should be required to notify you of the danger of long term impact of social  sharing on your personal privacy (and sometimes I also add two other factors: how many hours you are projected to spend "Facebooking" over the coming years and also how much peer pressure and social isolation you will endure if you want to leave the platform). In my lifetime, awareness has developed and legislation has changed such that cigarettes and cigarette advertisements are required to bear warnings about the health hazards: maybe I'll yet live to see awareness rise about the consequences of social sharing.

In contrast to smoking, social sharing done right actually helps rather than hurts. In fact, the rise of online social networking and social multimedia sharing has been downright amazing technological development. Moved by this awe, last year in a project proposal, I effused that social networks are, "...a virtual prosthetic that extends the strong fabric of social connectivity critical to the well-being and growth of human societies into the online realm."

That proposal developed the idea of "worry-free social sharing": a social sharing client that would gently alert us when our sharing actions, in ways we do not intend, threaten to compromise our privacy---and then suggest alternative actions, which allow us to share our personal experiences, but in a wiser way.

Yes, people are responsible for their own actions. But in some cases, we as individual users do not have the understanding of multimedia analysis technology, or of the power of algorithms to combine different sorts of data to reveal facts about us that we thought were hidden. We all would need such understanding in order to allow us to make informed decisions about which types of social sharing is harmless and which types should better be avoided.

Even for the most savvy of us there are always surprises: Did you know that if you upload a video to YouTube and you carefully avoid geo-tagging it, but if you happen to be in a city and capture an ambulance siren in the background, that siren will serve to indicate in which city you are? Check out the work on multimodal location estimation [1]. Maybe you don't care if the world knows where you are, but if you do happen to be worried about having left your house empty during your vacation, it would be good to know that you just about betrayed your location to the world without realizing it.  I've written about this before, e.g., in this post that mentions cybercasing.

It is within the reach of technology to build a "worry-free social sharing" client. The problem is getting the research funding to do so. Industry doesn't really have an interest in having users start being concerned about the implications of their sharing behavior. (It's in their interest to just send the message "share more".) Sure, it's unpleasant and possibly off-putting to have to reflect on the fact that someone might break into your house based on information about your location gleaned from videos that you post to YouTube. But is seems to me that "worry-free sharing" is an idea that users could identify with: just like the cereal box in the morning that announces how much fiber and how many vitamins we are consuming promotes consumption rather than driving people away from a product.

Another project proposal won the competition over the "worry-free social sharing" idea. One of the professors involved in the review later informed me that "worry-free social sharing" sounded like something female. I wasn't really sure what to do with that remark beyond thinking that it probably wasn't one of the considerations for the decision and storing it away for future reference.

I hadn't thought about the femaleness of privacy protection until this weekend, during the new Batman Movie. Here, we watched Cat Woman chasing something called "Clean Slate". She knows that what she needs in order to live her life the way she wants it is to make a clean break with the past. But Batman eventually recognizes this too. And I am happy to see other voices online interested in the privacy themes of the Batman movie. So I am not going to assume that there is only one half of the world population that would be interested in "worry free" sharing solutions.

Thinking about Batman also brought me back to the parallel with the cigarette warning label case. The label pictured above warns of the dangers of second hand smoke, "You're not the only one smoking this cigarette." If warning people about the dangers for their near and dear ones motivates people to cut back or stop smoking, maybe the same effect is true of social sharing. The "worry-free social sharing" client can remind us: Hey, you don't mind posting this picture, but maybe it will have unintended consequences for your friend, who is also pictured.

If you don't believe me, believe Batman: "You wear the mask to protect those you love."

Gerald Friedland, Oriol Vinyals, and Trevor Darrell. Multimodal location estimation. In Proceedings of the international conference on Multimedia (MM '10). ACM, New York, NY, USA, 1245-1252.

Wednesday, July 11, 2012

Time Machine Session at ICME 2012 and beyond

Today was the day of the Time Machine Session at ICME 2012. The session consisted of talks given by experts in the field of multimedia about "Time Machine Topics", defined as: ideas that were published before their time and have yet to reach their full potential. 

At first, it might sound like just digging around in the past and brushing off some old ideas. Or it even might sound like some futuristic science recycling scheme, designed to make the most of a limited resource.  

But a Time Machine Topic is far from dusty, outdated or rare. Instead, a Time Machine Topic is a topic that is currently experiencing renewed relevance because of subsequent developments in technology and also in our expectations and needs as users. 

We think that there are a large number of Time Machine Topics and that some of them bear repeated mention to support the integration of new researchers into the research community and also cross-pollination between related research domains.

The Time Machine Session was born at ICME 2012 because Mercan Topkara and I were appointed under the title "Innovation and Demo Chairs". To be honest, I had never heard of a position called "Innovation and Demo Chair" before. The "Demo" part seemed pretty straightforward, but "Innovation"? What could we possibly offer? 

We decided that our innovation should create something for the multimedia community that was new and that served a pressing need. With the Time Machine Session we set out to achieve a number of goals:
  1. Stimulate observation and discussion among researchers.
  2. Emphasize the benefits of knowing the literature.
  3. Streamline innovation by reducing redundancy.
  4. Encourage reproducing and reproducible research.
  5. Maintain the breadth of the solution space to stimulate new algorithms and approaches
For me personally, a major reason for proposing the Time Machine Session is to create a forum where we publicly and, perhaps a bit ritualistically, demonstrate that we as researchers value knowing the literature and knowing where we have been. 

Google Scholar reminds us that we "Stand on the shoulders of giants" and the Time Machine Session gives us as scientists an opportunity to remind ourselves of exactly whose shoulders those are (and there are lots of them). 

If Time Machine Sessions exist at conferences (and we hope that there will be more in the future at ICME and elsewhere) we think it will incentivize us as researchers to really study and understand the literature. It will ensure that the "Related Work" sections of our papers are a truly integral part of our research that contributes to the forward movement of our field.

I am making the slides I used for the opening of the Time Machine Session available in the hope that they might be useful for other people who want to hold other Time Machine Sessions elsewhere. In the slides, I discuss the session goals in a bit more detail and use plain language and some great mood-setting images. 

I wanted to explicitly point out that the images really made the introduction special, and here I owe much thanks on Auntie K on Flickr, who is so thoughtful to make some of her work available under a Creative Commons license.

The four talks in the ICME 2012 Time Machine Session were the following:
  • Dynamic Time Warping's New Youth (Xavier Anguera, Telefonica, Spain )
  • Designing Calm Technology (John N.A. Brown, Alpen-Adria Universität Klagenfurt, Austria & Universitat Politècnica de Catalunya, Spain )
  • Affective multimedia analysis (Mohammad Soleymani, Imperial College London, UK)
  • High Order Entropy Coding, (Wenjun Zeng, University of Missouri, USA)
More information on the talks can be found at the ICME 2012 website's expert talks page.

Also, John N.A. Brown creative a short documentary video at ICME 2013 about the Time Machine Session. The video contains people's reactions to the session and a bit more information on how and why we organized it.


The talks in the Time Machine Session were recorded by videolectures.net and is available at the bottom of the page at http://videolectures.net/icme2012_melbourne/ 

The opening is here:
   
Time Machine Session: Introduction

Martha Larson

The original call for proposals for expert talks is repeated below, or read it at: http://www.icme2012.org/CallForPapers_ExpertTalk.php 

Time Machine Session 
Expert Talks  on Innovating the Future Leveraging the Past
IEEE International Conference on Multimedia & Expo (ICME) 2012
11 July, 2012, Melbourne, Australia

Multimedia research is moving ahead in leaps and bounds. In order to pursue the most innovative and productive paths forward, we need an in-depth understanding of where we have already been. The Time Machine Session at the ICME 2012 is dedicated to the principle of improving the future by leveraging valuable insights from the past. The session will consist of a series of expert talks that re-introduce ideas that were published "before their time" and, as a result, were never fully exploited. A "Time Machine Topic" is distinguished by the fact that subsequent technological and social developments have led to a renewal of its relevance, making it currently of critical interest and value to the multimedia research community. A Time Machine Talk covers not only the original idea, but also explains why it currently deserves renewed attention and how it can influence the future of multimedia research.  We invite the submission of proposals for oral presentations in the ICME 2012 Time Machine Session.

Time Machine Talks should reflect expert-level understanding of the technological and social developments that have taken place in the field of multimedia and have brought about renewed relevance of past concepts. These developments include, but are not limited to:
  • Expansion in the volume, diversity and sources of multimedia content
  • Increase in the size, speed and sophistication of distribution networks
  • Improvement of computing infrastructures in terms of processing, storage and distribution,
  • Growth of the variety and capacity of user end devices
  • Development of user expectations for new multimedia applications
In sum, the goals of the Time Machine Session are to stimulate the creative thinking of today's multimedia researchers and to maintain the breadth of the solution space in which we develop new algorithms and approaches. Additionally, we believe that Time Machine Talks can help streamline and defragment the innovation process, by encouraging reproduction and reducing redundancy. Finally, we hope that the Time Machine Session will stimulate interesting and productive discussion in the community.

Selection
From the pool of submissions, a panel will make a selection of talks for presentation at the Time Machine Session. The decision will be made on using the following criteria:
  • Renewed relevance of the idea for today's multimedia researchers and research domains as set out in the general ICME 2012 CFP
  • Scope of the potential impact of the re-introduction of the idea on innovation in the multimedia research community
  • Importance of re-introduction of the idea to prevent the community from wasting time by "reinventing the wheel"
  • Presentation of the idea i.e., compelling argumentation and engaging presentation style 
Submission Format
The submission consists of three parts:
  1. The reference (i.e., bibliographic citation) of the paper that originally introduced the idea (pub-lished at least five years ago and still publicly available),
  2. A three minute video summarizing the idea and explaining why at the present moment its time is finally ripe,
  3. A 300-400 word abstract to accompany the Time Machine Talk in the ICME 2012 program. Note that the person submitting the proposal does not necessarily need to be one of the authors of the original paper.

Friday, June 1, 2012

Criteria for judging a demo in a conference demo session

Mercan Topkara and I are the "Innovation and Demo Chairs" for ICME 2012 to be held 9-13 July 2012 in Melbourne, Australia. We were called upon to organize the decision making process by which the ICME organizers would arrive at the decision of which demo would take home the ICME 2012 best demo award.

The decision is a difficult one because demos in the area of multimedia tend to be radically different in nature. For this reason, I formulated a list of six dimensions to use when judging demos.

1. Clarity: Understandability of the demo paper and the presentation.
2. Realization: Well implemented, robust, good use of technology.
3. Innovation: Addresses a problem that has not yet been tackled (or has proven difficult to solve).
4. Impact: The number of people the technology potentially touches and the importance of its influence on their lives.
5. Representativity: Centrality to the topics covered by the conference (in this case ICME)
6. Magic: How closely the technology fills the description, "Any sufficiently advanced technology is indistinguishable from magic" (cf. http://en.wikipedia.org/wiki/Clarke%27s_three_laws)

Number 6 is basically a wild card that makes it possible to introduce in a controlled way that factor of je ne sais quoi, which seems to slip into the considerations made when judging demos in any case.

In practice, another factor that always seems to be important is how close the demo is to a working system that is or is about to be deployed in the real world. Also, when judging demos it seems that one is always trying to project forward: how important will this technology be five or ten years from now? Will the passage of time reveal that it is a disruptive technology? (Or, as Wikipedia prefers to call it disruptive innovation?)

For a list of the demos to be presented at ICME 2012, see the ICME 2012 Demo page.

I am dating the post 1 June, when I formulated the list of criteria. It's later now, but time seems to have simply gotten away from me, not surprising given the ICME 2012 Time Machine Session.

Thursday, May 17, 2012

Search by misconception: Should search engines support information needs that are ill conceived?


The real Mozartkugeln? (Flickr: davidroethler)
Should our search engines make information findable based on misconceptions? Well, it's complicated. This post gives some examples to highlight the relationship of misconceptions to search.

Let's start with an example. When I refer to "Mozartkugeln" I mean the ones in the pictured here. They are gold and show Mozart in his red jacket. Their shape is round. I differentiate these from the ones with flat bottoms, which are for me "fake" Mozartkugeln.

My idea of Mozartkugeln can be considered a misconception. The original Mozartkugeln are apparently produced by a company called "Fürst" and are silver with a blue Mozart. Additionally, the producer of the flat-bottom ones apparently has the right to call their product "Real Reber Mozartkugeln". Digging on Wikipedia and on other websites supplied me with this information.

But what should an image search engine return in response to the query "Mozartkugeln"? Is it obliged to make an effort to resolve the question of which is the "real" Mozartkugel? Or is it fine if it just returns images that users have uploaded a tagged with "Mozartkugel"?

Effectively, simply returning images tagged with "Mozartkugel" allows users to search by misconception. The search engine returns images who have been tagged by people like me, who have a certain view on the matter (based on conversations with an Austrian roommate now a couple decades old and several subsequent trips to Austria, none including Salzburg), which is not necessarily universal. I am not immediately convinced that I can be satisfied with such a search engine as a source of information. Although, it seems reasonable to assume that if enough voices are combined, a consensus will emerge. I noticed that if you search for "champagne" on Google images, the top hits (at least the ones that depict identifiable bottles) clearly hail from the Champagne region in France and don't include the large range of other bubbly wines from other corners of the world that are widely enjoyed under the name "champagne".

In short, allowing search by misconception seems relatively innocuous. But we should be careful about assuming that the Mozartkugeln example is the end of the story. What is unique about this example, is that the search engine is relatively transparent in the way that it works. The images are returned by seeking exact matches in their user-assigned tagsets; without such a match, the image is not relevant. Users of the search engine have a chance of being at least vaguely aware of the reason for the match and they can propagate their understanding of the reliability of the taggers to create an understanding about the reliability of the results.

However, when the search engine becomes more sophisticated, the situation quickly gets quite murky. For example, if I had a visual concept detector that was trained to detect Mozartkugeln in images and assign to them the appropriate tags. The design of the detector would require collecting examples of Mozartkugeln, which means that whoever trains the detector holds the ultimate control over deciding what a Mozartkugel actually is.

The example of Mozartkugeln is interesting. In some cases, one could argue that common sense knowledge will tell you what an object is, for example, a helicopter or a pram. Everyone can identify these objects, right? But in the case of the Mozartkugeln, there is no right answer. It depends on your perspective. A long discussion will arrive at the conclusion "It's complicated". (And you may already find yourself with the same issue for the pram, if not actually the helicopter.)

It seems like a good idea to do away with the central authority that collects the examples used to train the detectors. After all, no one really likes they guy who walks around the party reminding people, "Yes, but it's not real champagne".

But do we really want to admit search by misconception? I had quite an unsettling experience with Google's query suggestion. On 17 May 2011, I was looking for a news story on one of the Facebook founders have renounced his US citizenship. No sooner had I typed in "facebook founder" did Google present me with the following list of suggested queries:

facebook founder mark
facebook founder saverin
facebook founder buys new republic
facebook founder college
facebook founder gay
facebook founder bios
facebook founder dead
facebook founder movie

Did I really need to know about the existence of the circulating rumors? Do I go on to passively "believe" a query or do I dig deeper that find out if it is true? Do we really want our search engines to allow us to so easily flow down the same information paths worn by searchers before us who mis-received a rumor?

In the case of "facebook founder dead" I did dig deeper. That query led to a Fox News article on the death of Ilya Zhitomirskiy, one of the co-founders of Diaspora*, an alternative to Facebook. I was left wondering at how query suggestions have taken on an information dissemination (news broadcast, if you will) role of their own.

From the fun of searching for pictures of bonbons (...and wondering if round vs. flatbottom Mozartkugel relates to a real misconception or rather an alternate interpretation) we hit on a matter of true importance (Diaspora* upends the Facebook model because it is based on the idea that every member of the network should “own” his personal information). Suddenly, it gets extremely serious. In light of this seriousness, it looks like if we really do not want search engines to admit search by misconception at all.

This whole line of though was started while I was at a symposium entitled "Cultural Heritage Gets Social" of the SEALINCMedia project (Socially-enriched access to linked cultural media). Alice Warley (Public Catalogue Foundation, UK) gave a talk entitled "Your Paintings Tagger: Crowd-sourcing, art history and the UK's national oil painting collection" about a website where visitors collaborate to tag painters. 

Apparently, general public users tend to tag older paintings "formal wear" when what the people pictured in the paintings are wearing is not formal wear at all, but rather daily clothing.
The reason for this misconception is that today's formal wear evolved from what was worn on a daily basis in certain social circles in past eras. Wikipedia is rather silent on the history of formal wear. The "misconceptions" of the taggers are actually a source of information about something that is not widely known, but actually an real historical connection.

So we're back to the Mozartkugeln, considering whether Mozart is dressed for a concert, or is in his everyday work clothing that he uses for composing. It seems like misconceptions help us to uncover new and interesting information.

However, if we incorporate misconceptions, maybe we should call them 'exploration engines'. A 'search' engine should find answers or else gently reveal to us that our initial information need was ill conceived.

Saturday, April 28, 2012

English usage convention for scientific publications: "Related work" vs. "Related works"

Yesterday, we got back reviews for a journal article where a reviewer suggests that we change the title of our Section 2 from "Related Work" to "Related Works". In the review, the comment was included in a list headed "Typos (I think)" so the reviewer is not sure exactly what is going on. The reviewer's self doubt is well founded:

In the context of a review of previous research on a topic in a scientific publication, "related work" is the correct expression and not "related works".

There are several places on the internet that provide clarity on this point. Typing a query "related work" vs. "related works" into your favorite search engine will give you nice set of pages asking you to please use "related work" and not "related works" when writing a scientific publication. Examples are:

http://www.cs.columbia.edu/~hgs/etc/writing-bugs.html
http://www.iaria.org/editorialrules.html

I'm not trying to add another link to that list with this blog post. Rather, I want to add a couple of comments about why the distinction is important.

"Work" can be used as either a count noun or a mass noun. Mass nouns refer to undifferentiated substances, which can not be conceptualized as individual entities and, for this reason, it does not make sense to use such nouns in the plural. "Fuel" is a mass noun. Count nouns refer to entities that are discrete and differentiable and are, for this reason, countable---such such nouns can be used in the plural. "Airplane" is a count noun.

So, I suppose, as an author of a scientific paper, you are free to choose whether you consider research work to be an undifferentiated substance or set of discrete entities and choose "related work" or "related works" accordingly. Why then, is it so disturbing to read "related works"?

I thought about this point a bit and I realized that it is disturbing because the difference has some pretty profound implications for how we conceptualize scientific research. Is our scientific output making a contribution to a mass of knowledge, joining the efforts of scientists that went before us and available to those who go after? Is it meant to be tapped by others, reproduced and extended? For me the answers are "yes" and "yes'. The results of scientific effort flow together to become an undifferentiated resource pool whose value lies in how it advances the collective knowledge of the species and how it can be put to productive use. Under this conceptualization of scientific work, it is only possible to use the mass noun, which does not ever occur in the plural.

The expression "Related works" evokes a conceptualization of scientific work as a set of discrete entities, individual units of output created by the efforts of individuals with the idea that they will remain untouched in their individuality. Under such a view, each paper published would be a work of art, embodying the creative force of an individual researcher or an individual team and intended to be admired, rather than built upon, reproduced, validated or improved. Indeed, when the art world makes the plural of "work" they say "works" as in "works of art". These are clearly individual entities, finished works, ready to hang on the wall of the gallery.

We do sometimes feel this way about our work as researchers: our biggest and best conferences have the exciting, invigorating atmosphere of an art show opening, where you get to meet the great creative spirits and enjoy wonder and admiration at what they have produced. However, after the conference, we go home and take these amazing new papers apart and work with them in a way they makes clear that we see them as substance to be extended and not as finished works meant for framing and hanging on the wall.

So, please, yes, it's "related work". You probably already know that deep in your own scientist soul. You really wouldn't ever write "related researches" would you? "Research" is of course also a mass noun, also denoting our scientific effort and underlining its part of a larger flow.

At a more general level, I do sincerely believe that we should all adopt World English: drop some of the finer points about word choice and grammar conventions and just write papers in clear simple sentences that can be easily understood by anyone with a working grasp of the language. However, for a "work" vs. "works" distinction remains, in my opinion, an important one: it gives us a chance to reflect on how we conceptualized our contributions to our scientific field. Maintaining the distinction allows us to continue to express a subtlety important to our underlying scientific culture and mission.

Monday, March 12, 2012

The MediaEval Workshop: What it's meant to be and why you want to be there.

The MediaEval workshop is the event held each year in the fall at the culmination of the yearly benchmarking cycle. At the time of the MediaEval workshop many things have already happened in the benchmarking year: The task organizers have worked hard to define tasks and issue data sets. Participants have worked hard to develop algorithms that tackle the tasks, and they have run these algorithms on the data sets. The "runs" have been evaluated and each participating team has written their working notes paper. Now it's time for the workshop!

This blog post provides a view (from my perspective as one of the MediaEval co-ordinators) on the history of the workshop and on what the workshop is meant to be. In particular, it highlights the similarities and differences with other types of workshops.

The main goal of the MediaEval workshop is to bring everyone who carried MediaEval tasks together in one physical location to present and discuss their results, exchange experiences and develop ideas for how to improve their algorithms. The first year that we met at a medieval convent, Santa Croce in Fossabanda, it was mostly due to delight in the wordplay between medieval and MediaEval. However, we soon came to appreciate how getting everyone together working, eating and basically living in the same space creates an extremely productive focus on our our common tasks and goals. (Although unlike the nuns of the Middle Ages we don't go dashing off to prayer when we hear the convent bell.)

In 2010, we held the MediaEval workshop just before ACM Multimedia 2010, which was held at the Palazzo dei Congressi in Firenze, Italy. Santa Croce in Fossabanda is located in Pisa, about an hour's train ride from Firenze. We chose the dates and place to cut down on travel time and cost for people who wanted to attend both ACM Multimedia 2010 and the MediaEval 2010 workshop.

The next year, Interspeech 2011 came to the Palazzo dei Congressi in Firenze about the same time of year. MediaEval submitted a proposal and was granted the status of an "Official Satellite Event of Interspeech 2011". Now, instead of just taken advantage of the convenience for travel, we began emphasize hook-up to the topic of the conference: being associated with Interspeech reinforced the use of speech within MediaEval and helped us to better realize the goals expressed in the MediaEval slogan The "multi" in multimedia.

This year, the 12th European Conference on Computer Vision (ECCV 2012) will be held in Firenze. This conference provides us with the opportunity to reinforce the use of visual content within MediaEval, another of the multimedia "multi's". The MediaEval 2012 Workshop will be held right before this conference starts, again in Santa Croce in Fossabanda in Pisa. A very close contending idea for the MediaEval 2012 workshop was to hold it near 13th International Society for Music Information Retrieval Conference (ISMIR 2012) in Porto. However, the results of the MediaEval 2012 survey showed that the majority preferred to co-ordinate the date and place with ECCV 2012 and stay for a third year in Pisa.

In sum, the idea of being close to a large conference related to MediaEval topics has grown from being a convenience to being an aspect that strengthens and enriches both the benchmark and the workshop.

What exactly happens at the MediaEval workshop? The workshop consists of a series of sessions on the individual tasks. The task organizers present the task as a whole and each team presents its individual results, after which the floor is opened for discussion. More discussion and exchange occurs during meals and breaks in ad hoc groups. We try to build in a lot of space for discussion into the workshop schedule and especially try to create opportunities for students to discuss with more experienced researchers who help them to guide their efforts along the most effective path.

The proceedings are an important aspect of the workshop. The MediaEval workshop proceedings is a "Working Notes Proceedings" and consists of short (two page) papers written by the participating teams to report their results. These papers describe the algorithms that are used and present the results. They then also seek to understand the algorithm, and participants are requested to report:
  • which cases are easy/difficult and why
  • which approaches work best and why
  • which approaches do not work well
The working notes submissions are reviewed by the task organizers. The task organizers may either accept the submission as is, or may come back to the participant team with a request for revisions of the paper. The preferred mechanism is to have the papers revised rather than to reject them --- sometimes this revision cycle means that the working notes proceedings is not ready until just before the workshop. For this reason, the working notes proceedings is distributed at the workshop on a memory stick.

After the workshop, the working notes is made available online. The 2011 the "Working Notes Proceedings of the MediaEval 2011 Workshop" was published here: http://ceur-ws.org/Vol-807/ and in the future we would like to continue to use http://ceur-ws.org/. By publishing in this way, the copyright for the individual papers is with the papers' authors.

MediaEval working notes papers are intended to be first versions of work that is later extended by the authors and submitted to mainstream venues, such as conferences and journals. The fact that the MediaEval workshop proceedings consists of short working notes and that the copyright does stays with the authors keep the proceedings consistent with the goal of reporting an initial research result, which will then be refined and extended using input from the discussion at the MediaEval workshop.

Another important goal of the workshop is to discuss the tasks themselves. Did they help to move the state-of-the-art forward? Should we improve or replace them next year? Are their new questions that need to be answered that require new tasks. Any one attending the workshop is welcome to stand up in the final session and "pitch" an idea for a new task. Tasks which receive good community support in this session have a good chance of receiving the response levels they need on the yearly MediaEval survey to run as tasks in the next year.

Finally, the workshop also aims to connect ourselves and our research to the larger community. We welcome participants from industry who have tasks that they might want to pitch to the community. We also welcome representatives from other benchmarks: MediaEval grows stronger by staying in close contact with groups running benchmarking activities in areas beyond the MediaEval core domain of human and social multimedia. MediaEval 2011 was presented at CLEF 2011, NTCIR 2011 and FIRE 2011 and in 2012 we hope to convince some of our sister benchmarks to give a reciprocal presentation on their own experiences.

As part of staying connected to the larger community, the MediaEval 2011 workshop included a poster and demo session where projects that help to organize MediaEval tasks could present their results and where industry people could make a presentation of new and interesting problems that they would like to make known to the MediaEval community as possible benchmarking tasks.

The workshop closes with a gathering of task organizers and others who have invested time and effort into the community or want to get more closely involved in the future. During this session, we reflect back on what happened so far in the benchmarking year and also discuss the MediaEval related activities that we organize beyond the core benchmarking activities. These include joint papers among all the participants of a task and also special sessions at conferences. Looking forward we also plan to get involved in organizing more workshops (of the traditional variety) at conferences and also think about the possibilities of special issues. Finally, we reflect on our MediaEval goal, To offer the community innovative new tasks related to the human and social aspects of multimedia and our slogan The "multi" in multimedia (it not necessary to be able to say the slogan with a straight face.) On the basis of these reflections, we consider where we would like to go with the benchmark in the coming year.

So why do you want to be at the MediaEval workshop? Well, if you are a task participant, it gives you an opportunity to exchange with other people working on topics similar to yours and helps you to understand and improve the algorithms that you are using to approach your task. MediaEval needs a central group of dedicated researchers to organize the tasks that make the benchmark run. Attending the workshop is a good first step to getting more deeply involved in MediaEval, for example, by proposing a task for the year.

On the MediaEval 2012 survey, we had a question concerning what the community thinks about how MediaEval should grow. I personally, want to keep the workshop as small and intimate as possible. In 2011, we had nearly 60 people and that appeared to me to be a good maximum size for the workshop. However, when I examined the survey results, I realize that I am in the minority here, and that most of the people in the community would like growth. As a result, I am changing my opinion and we will not attempt to artificially restrict growth, as long as it is sustainable.

The issues and ideas around growth is just one area in which the concept of the MediaEval workshop is evolving. One of MediaEval's strengths is that it develops from year to year, guided by the input of the community --- and in particular those people who invest the most hours of their time to make it work. I look forward witnessing and being involved in this development in the 2012 season and, we hope, to seasons beyond.

For further impressions of the MediaEval workshop, check out the MediaEval 2011 workshop video: