 How many hours do I spend writing deliverables and reports? I'd rather not count. Here I am on Friday night with a to do list left over from the week that seems only very vaguely connected to my main mission as a researcher, namely to improve multimedia access systems, especially for spoken audio and video with a speech track.
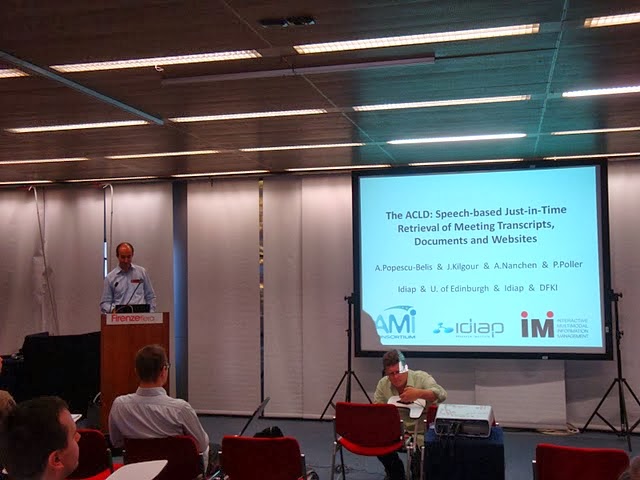
Sometimes it takes writing a blog entry to refocus on the core values of multimedia search. I was going through the pictures from the Searching Spontaneous Conversation Speech workshop in order to find a good one to add to the latest newsletter report, and dang it, if there weren't so many speaker pictures that we ruined because Florian is crouching in the middle in the front, tending to the laptop that we were using to capture the sound.
At Interspeech we discussed the idea of simply recording all the spoken audio at both the MediaEval 2010 workshop and the SSCS 2010 workshop in order to start an audio corpus of workshops to use for research on meeting retrieval. It sounded like a good idea that we would never have the time to pull off, but sure enough, there we were in Italy, and a network of people came together and brought sound equipment from all over and we had ourselves a system for audio capture. I remember the satisfaction in his voice, when Florian announced "We are now recording six channels". Actually, I remember it because I listened to it on the recording afterwards as we started the laborious process of post-processing and I wondered "Gee, what kinds of things were we talking about next to the main presentations."
So here's the refocus. Florian isn't actually ruining the picture. His presence actually underlines what the speaker is talking about -- the slide reads "The ACLD: Speech-based Just-in-Time Retrieval of Meeting Transcripts, Documents and Websites". We have made such a huge step in this direction that in are own lives we can simply decide to capture our spoken content, everyone at the workshop says, "OK, that's cool" and bang we have more data than we know what to do with.
We also did this at SSCS 2008 in Singapore. The videos were online for a while -- we transcribed them using Nuance Audiomining SDK for speech recognition and made them searable with a Lemur-based earch engine. For awhile, we could visit a website and search our own dogfood, as it were. It seems, however, that the multimedia lifecycle got the better of our content: the system was not maintained and now the videos are no longer available online. I don't know if we'll do much better this year, but the point is that we keep on trying. And we have Florian in the middle of the workshop picture reminding us that this attempt may be time consuming, but it is constitutes the core of our research mission.


